Partial Observability in LLM Agent Environments Using Third-Party APIs
LLM agents using third-party APIs face hidden failures across sequential tool calls.
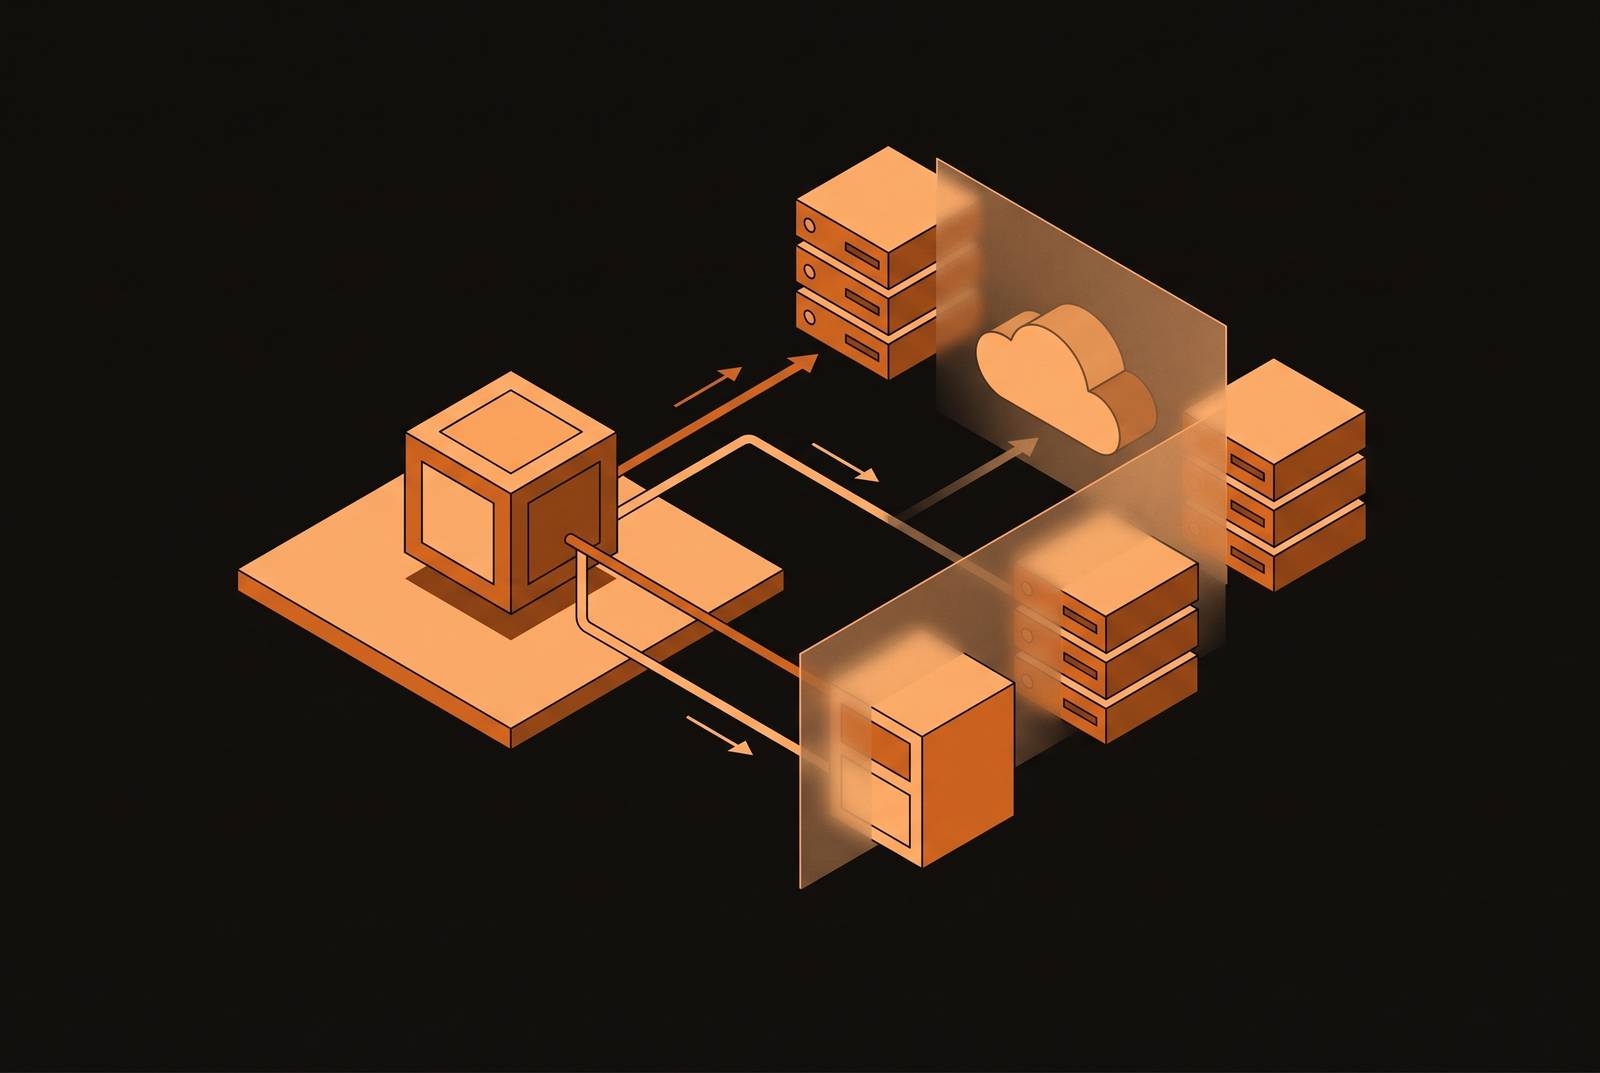
LLM agents built around multi-step tool use are structurally partially observable: at every point in a workflow, an agent sees only what an API returns at that moment, not the provider's full internal state, not queued webhooks, not a race condition unfolding in parallel. This isn't a gap in logging or a missing config flag. The agent branches, retries, and adapts its plan based on whatever intermediate response it just received, so the world it reasons about is, by construction, always an incomplete snapshot of something larger and still in motion.
The structural observability problem for LLM agents using third-party APIs
An agent calling a payment API, a ticketing system, or a prediction market doesn't get a window into that provider's database. It gets a response: a JSON payload, a status code, maybe a webhook later. Everything the agent knows about the state of the world downstream of that call has to be inferred from that one response, and the response is a snapshot taken at a single instant in a system that keeps changing after the snapshot is taken. A race condition between two sequential tool calls can produce an intermediate state the agent never directly observes but still has to act as though it understands. An upstream schema change can hand back a payload that's structurally valid, parses cleanly, and still means something entirely different than it used to, so the agent keeps reasoning forward on a premise that's already wrong.
None of this appears as a crash in the agent's output. The agent can write a coherent plan, pick a sensible tool, pass parameters that are perfectly well-formed, and still act on a version of the world that no longer exists. The defect isn't in any single call. It lives in the relationship between two or more calls made in sequence, where the gap between what the agent last saw and what's actually true has widened without any signal announcing it. Systems built for deterministic request-response testing have no native way to represent that gap, because there's no single malformed request or broken response to point to. The failure is relational, and relational failures are invisible to tools designed to check one call at a time.
Observability tooling's limits against partial observability in agent testing
The observability layer for LLM agents has matured fast, and the leading tools are genuinely good at what they do. MLflow's tracing captures full execution traces, including tool calls, reasoning chains, and planning decisions, and its mlflow.genai.evaluate() API scores tool selection, plan quality, and logical consistency across an entire reasoning loop. LangSmith gives deep trace visibility into agent reasoning, tool execution, and token usage inside LangChain and LangGraph setups, and it lets an engineer send individual runs from a failed production trace into a Playground for prompt iteration, with its Engine feature able to replay failed traces against a deployment to confirm a fix actually worked. Langfuse offers framework-agnostic session threading with self-hosted deployment, which matters a great deal to teams working under data residency requirements.
All three do real work, and none of them can do the one thing partial observability demands: put an agent into a specific, controlled API state, such as a world where a particular webhook has been dropped, a rate limit is one call from firing, or a Stripe invoice sits in a partially-refunded state, and then run the agent through that exact scenario before any of it touches production. Observability tools record what already happened. They can't manufacture the state sequence that caused a failure and hand it back to an engineer to test against on demand.
The failure class that matters most here is quiet. An agent receives an HTTP 200, the response is structurally valid, and it still reflects a partial or stale version of the underlying state. A trace tool will faithfully record what the agent did in response to that 200. It has no way of knowing the 200 itself was already wrong relative to the true state of the system at that moment, because judging that requires a reference point the trace doesn't carry. Evaluation frameworks run into the same limit from a different angle: scoring tool selection and plan adherence against a trace, the way MLflow's agent evaluation does, requires a trace to already exist. The failure has to have already happened somewhere for the scoring to have anything to work with. That's a real strength for catching regressions after the fact. It is a separate layer of work: exposing these failure modes before an agent ever reaches a live environment.
What makes a testing environment adequate for partial observability
Reproducing a partial-observation failure on demand requires an environment that remembers state across a sequence of calls. If the environment can't do that, there's no way for it to express the failure modes that actually matter, because those failures are defined by what changed between one call and the next, not by what any single call looked like in isolation.
Stateless mocks work by matching request shape to a predefined response. A mock will answer GET /orders/42 the same way regardless of whether a prior POST /orders/42/cancel was ever issued, because the mock has no memory of that prior call. That breaks down exactly where agent reasoning depends on continuity: an agent that creates an invoice and later checks its status is depending on the fact that the second call reflects the first, and a stateless mock simply has no mechanism to carry that dependency forward. Race conditions between sequential calls can't be expressed at all in this model, since the mock has no notion of time-ordered state transitions to begin with. Webhook delivery is worse still: webhooks are asynchronous, stateful, and triggered by something, and a mock with no persistent world has nothing to trigger them from.
A stateful simulator holds a persistent world for the length of a session. Create an invoice, and it exists somewhere real for the duration of the test. Cancel it, and every later read reflects the cancellation. Fail to acknowledge a webhook, and the simulator re-queues it on the same retry schedule the live API actually uses. That difference is what makes a scenario like a Stripe checkout testable at all: the agent has to handle the gap between a synchronous payment intent response and a webhook that fires three seconds later to actually fulfill the order, and a stateless mock has no way to represent that gap because it has no sense of elapsed time or pending events.
Two other common approaches fall short for related reasons. Recorded cassette approaches capture a real sequence of API responses and freeze it in place, so the sequence can be replayed but never varied: no fault can be injected mid-run, and the recording quietly drifts out of date as the real API keeps changing underneath it. Live sandboxes from API providers, like PayPal's, are genuinely stateful but not controllable in the way testing requires: they go down without warning, enforce real rate limits, need live credentials to use, and can't be reset to a specific known state on demand for a specific scenario.
How stateful, verified simulators make partial-observation failure modes reproducible
A stateful simulator that's continuously checked against the real API gives engineers something a mock or a cassette can't: a stand-in they can control and inspect, built to reproduce partial-observation failures on demand, before anything reaches production. Reproducing these failure modes in testing requires an environment that can isolate and vary API state sequences deliberately, something stateful simulators with fault injection support make possible by dropping a webhook, adding latency, or placing an agent into a specific intermediate state that would otherwise take hours of live testing to stumble into by accident.
Statefulness makes deterministic replay of multi-step scenarios possible. An engineer can define a world, say three open GitHub issues, one pending Stripe invoice, and a Slack channel with unread messages, seed the simulator with that exact world, run the agent through it, and run it again later with the world unchanged, so the two traces are directly comparable because nothing about the starting conditions moved between runs. Fault injection has to be treated as a core feature rather than an afterthought: injecting a 429 mid-sequence, a 503 on the third call, or a latency spike right at webhook delivery tests an agent exactly where partial observability does the most damage, in the middle of a state transition, when the agent has an incomplete signal and has to decide what to do with it anyway.
An empty environment doesn't teach an agent much. Rystic ships its simulators with pre-seeded realistic data, including a large open-source GitHub repo and recorded Kalshi markets, so an agent encounters something that resembles production. What separates a real stateful simulator from a merely elaborate mock is verification: a simulator that isn't checked continuously against the live API will drift quietly, start returning responses that no longer match how the real API behaves, and give engineers false confidence in exactly the cases where it matters most. Rystic verifies each simulator against the real API per commit from CI and publishes fidelity scores alongside that verification.
Fidelity at the level of individual API mechanics turns out to matter a great deal. Kalshi signs requests using RSA-PSS, not HMAC and not RSA PKCS#1 v1.5, and PSS adds randomized padding so that two signatures of the identical payload won't match each other, by design. A simulator that gets this wrong produces failures that look like authentication bugs rather than the state-related bugs they're meant to surface. Kalshi also moved to a token-bucket rate-limit model on 2026-04-23, with seven tiers and two independent buckets per tier, and it doesn't return a Retry-After header, so an agent tested against the old model will mishandle throttling under the new one without anyone noticing until production. Stripe can retry an undelivered webhook for up to three days, and PayPal retries failed deliveries several times over a similar three-day window while requiring an HTTP 2xx acknowledgment to stop. A simulator that doesn't reproduce those retry semantics can't expose the race conditions those retries create. Rystic's simulators run locally or in CI without needing live credentials or hitting real rate limits, so when a test fails, it means the agent's code is broken.
Specific partial-observation failure modes engineers can now reproduce
The failure modes worth testing for are the ordinary mechanics of async, stateful APIs, the kind a stateless test environment simply has no vocabulary to express, as the following cases show.
Missed or delayed webhook: an agent initiates a Stripe payment intent, gets the synchronous confirmation back, and then depends on an asynchronous webhook arriving later to actually fulfill the order. To test it, seed the simulator with a pending payment intent, configure webhook delivery to fail, run the agent, and check that it enters a waiting or retry state instead of proceeding as if the order were already fulfilled. An agent that mishandles this will either fulfill an order twice or sit blocked indefinitely in production, and neither failure leaves behind a clean error trace to point at afterward.
Race condition between sequential calls: an agent reads a GitHub issue, decides to close it, and sends the close call, but in the interval between the read and the write, another agent or process has already closed and reopened the same issue. The test seeds an open issue, injects a close-then-reopen transition between the agent's read and its write using the simulator's own controls, and checks that the agent handles the conflict response, treating a stale success as evidence of an unresolved conflict.
Stale state in a prediction market: a market the agent is reasoning about has already resolved, but the agent is working from a listing that hasn't caught up. The test pre-seeds a resolved market, presents the agent with the stale listing anyway, and checks that the agent verifies market status before placing an order. Rystic's Kalshi simulator reproduces the token-bucket rate-limit model introduced on 2026-04-23, including the missing Retry-After header, so an agent that naively retries on a 429 without any backoff logic will surface that failure inside the simulator long before it ever reaches a live market.
Schema drift mid-integration: an upstream API adds a required field to a response schema, and the agent keeps running without it because it was never written to check for the field's presence. This kind of drift isn't theoretical: the Kalshi Python SDK's nightly spec-drift check on 2026-10-06 found new required fields, price_level_structure and price_ranges, added to the upstream MultivariateEventCollection schema, along with a new optional market_id field on perps order requests. When a simulator is updated to reflect changes like these, agent tests that were passing the week before start failing, surfacing the integration gap while there's still time to fix it.
For payment providers specifically, run a regression checklist on a fixed schedule: pin the API version, then run the success, decline, expiry, refund, dispute, and duplicate-callback cases in sequence, and check explicitly whether a missing field causes the agent to raise an error or silently continue past it. The faults that do the most damage in production share one trait: they return a perfectly valid HTTP 200 while carrying state that's partial or already stale, and they're hard to catch for the simple reason that no error signal ever fires to flag them.
This testing infrastructure's importance for RL environments and AI agent evaluation at scale
Partial observability does more than cause occasional bad decisions in a single agent run. Inside a reinforcement learning environment where an agent calls external tools as part of its action space, partial observability corrupts the reward signal itself, since the agent is being rewarded or penalized based on a state it never fully observed in the first place, which makes the resulting policy unreliable almost by construction.
Running real-world APIs at the scale RL training demands isn't realistic to begin with. Rate limits, the need for live credentials, and sandbox downtime that shows up without warning make it impossible to run thousands of parallel training episodes against live endpoints without constant interruption. RL environments need a few specific properties that live APIs and recorded cassettes can't provide together. They need determinism, so the same action taken in the same state produces the same result every time, since a simulator whose responses drift or behave unpredictably feeds noisy gradients straight into training. They need controllable state, so a training harness can reset the simulator to a known baseline between episodes, seed it with a specific scenario, and inspect its internal state directly to construct a reward, none of which a live API or a frozen cassette allows. And they need to run at horizontal scale, across thousands of parallel containers, each one independent, with no shared state bleeding across runs and no rate limit from one container affecting another.
These are the same properties, controllable state, horizontal scale, fault injection, that make Rystic's simulators useful for RL training, and they are what large-scale agent evaluation pipelines need as well. Frameworks like MLflow's mlflow.genai.evaluate() score tool selection and plan adherence across a full execution trace, but a scorer is only as good as the environment that produced the trace it's scoring. A stable, inspectable simulator is what lets those scores mean something consistent across thousands of runs, rather than reflecting whatever a live third-party API happened to be doing that particular day.