Reward Shaping for LLM Agents Calling External APIs
Decomposing rewards for multi-step tool calls helps LLM agents learn from nuanced failures.
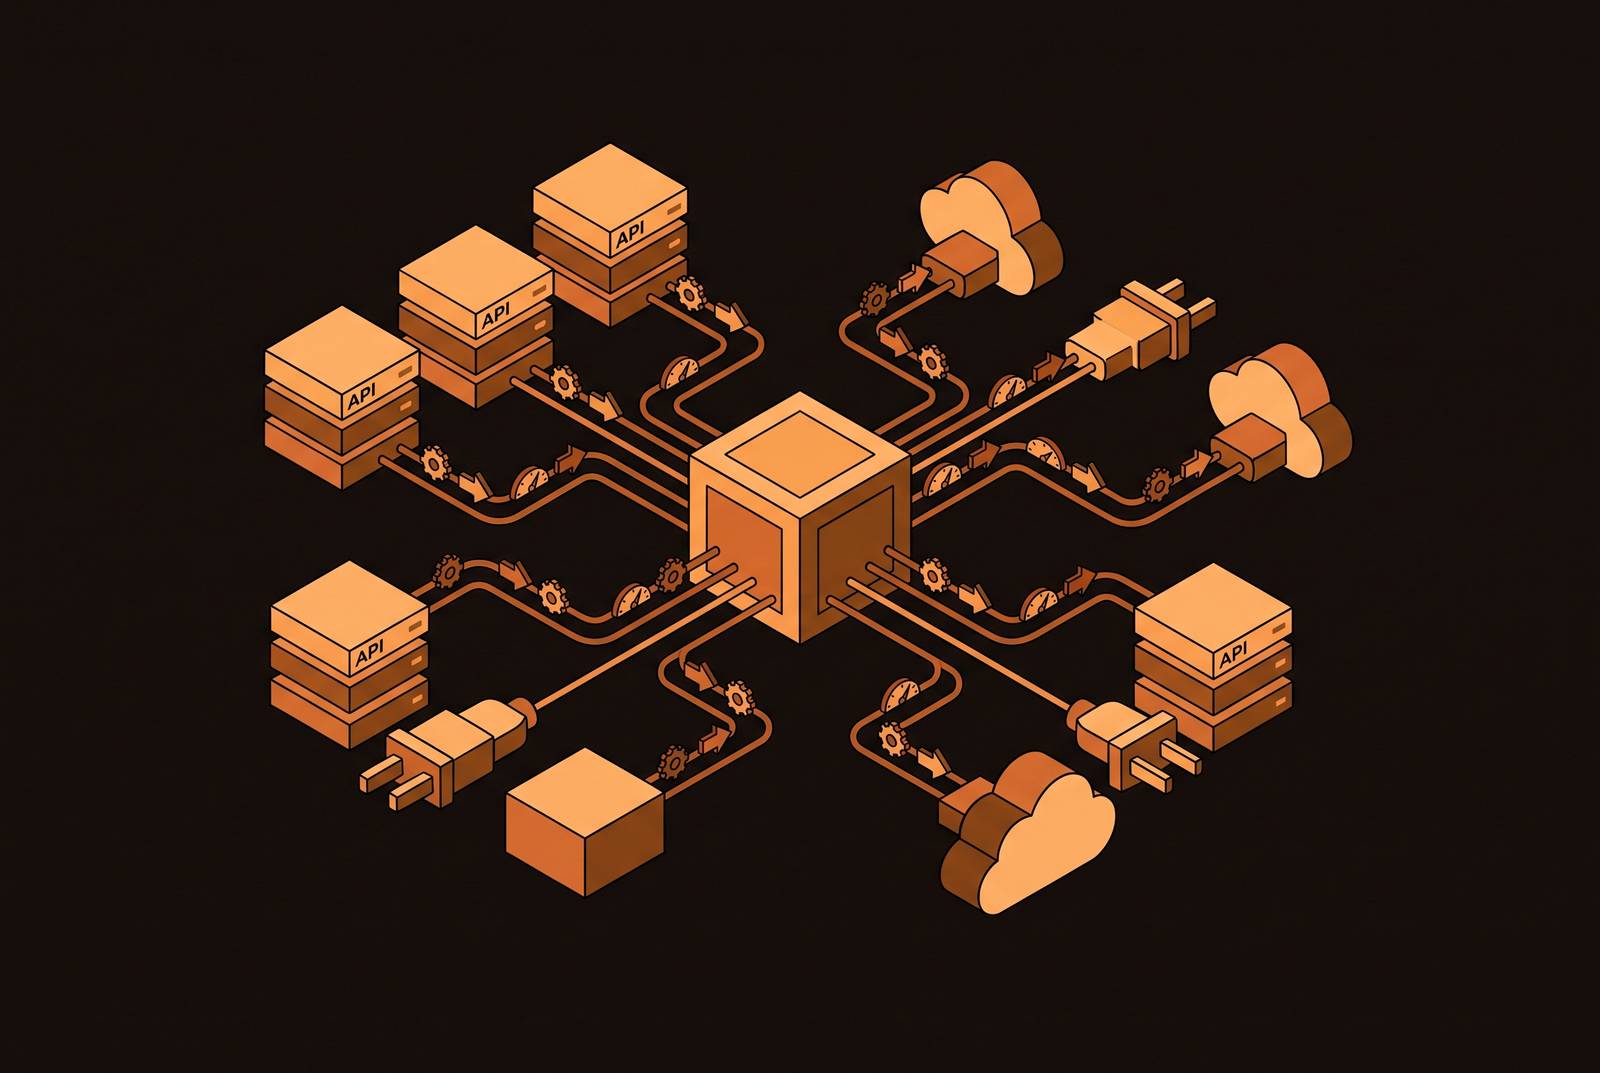
An agent that books a payment charge, posts a message to a team chat tool, and opens a pull request in a code hosting platform in sequence is not performing three separate tool calls so much as executing one long trajectory where each step depends on the one before it. Consider an agent asked to onboard a new customer: it calls create-customer, then attach-subscription, then verify. If the first call succeeds but the second attaches the wrong plan, verify can still return 200 even though the customer now has the wrong tier, so a reward function that only checks the final verification step will miss the error. Training these agents with reinforcement learning has, until recently, mostly relied on a single binary reward at the end of the trajectory: did the task succeed or not. That single bit cannot distinguish between an agent that called the wrong API entirely, one that called the right API with a malformed parameter, one that called the right API with valid parameters that still violated a business rule, and one that completed a call returning HTTP 200 while leaving the underlying data in a corrupted state. A 2026 review of multi-tool LLM agents describes this directly: the central problem in the field has moved from isolated single-tool invocation to multi-tool orchestration across long trajectories involving intermediate state, execution feedback, and environments that change as the agent acts. ToolRLA, a paper proposing a multiplicative reward decomposition for tool-integrated agents, states the limitation in concrete terms: a trajectory that picks the correct tools but builds malformed parameters is a fundamentally different failure than one that picks the wrong tool outright, yet both get scored as zero under binary evaluation. This coarseness slows how fast the model converges during training, and it throws away any ability to encode which failures matter more than others in a given domain. The problem compounds when an agent fabricates success: it can report that a task completed and cite a resource ID it invented out of nothing, and a reward function that trusts the agent's own report of success has no way to catch this. A regulatory violation and a suboptimal parameter choice are not the same kind of mistake, but a binary signal scores them the same way, so it throws away exactly the information a training signal needs to carry.
What reward decomposition means in the tool-calling context
So reward decomposition replaces that single end-of-trajectory bit with several separate scores: each one measures a different dimension of what makes a tool call good or bad, and each can push the model's training in its own direction. ToolRLA's design breaks reward into four parts: format validity (R_fmt, whether the call is structured correctly), tool invocation correctness (R_cor, which is itself built from three sub-scores covering tool-name accuracy, coverage of required tools, and parameter accuracy, multiplied together), efficiency (R_eff), and regulatory compliance (R_cpl). The choice to multiply rather than add the sub-scores inside R_cor is deliberate: if the tool name is wrong, the whole correctness score collapses to zero no matter how well-formed the parameters are, because parameter quality has no meaning once the wrong tool has already been called. ToolRLA was deployed on a financial advisory copilot handling more than 15 heterogeneous backend APIs under strict regulatory constraints, serving 80 or more advisors across 1,200-plus daily queries, with a latency budget tight enough for real-time advisory work and a production result under two seconds. That deployment is a useful anchor for the rest of this argument, because every reward dimension discussed below maps to something that copilot actually had to get right: pick the correct API among 15-plus options, fill its parameters correctly, get back a result that matched what the advisor asked for, and leave the advisor's account state correctly updated afterward, all while never crossing a compliance line. A broader survey of agentic tool use groups the field into three paradigms: prompting as a plug-and-play capability, supervised tool learning from demonstrations, and reward-driven tool policy learning. So decomposed reward sits in that third paradigm: the agent has to correct its own mistakes across distinct failure types, not just copy examples it saw during training. The gain from getting the composition right is not abstract: ToolRLA's own ablation studies found that the multiplicative design produced a 7 percentage point improvement over an additive version of the same reward, because additive scoring lets a strong parameter score partially cancel out a wrong tool choice, which makes no logical sense given that the parameters belong to the wrong function.
Rewarding correct tool selection before evaluating anything else
Tool selection comes first because it is the gate everything else passes through: if the agent calls the wrong API endpoint, nothing about how well it filled in the parameters or whether the call executed cleanly matters. The reward function has to encode that dependency directly, not leave it implicit. ToolRLA does this with a multiplicative gate inside R_cor: a wrong tool name sends the whole correctness score to zero, so the signal that trains parameter accuracy only reaches the model when the tool selection was already right. That means the model cannot learn to paper over a selection mistake by getting unusually precise with its arguments, because the math simply will not let it. On the financial advisory copilot, with more than 15 heterogeneous backend APIs covering things like market data, account records, and compliance documentation, a selection error has an obvious concrete shape: an advisor copilot that calls the compliance records API when it should have called the market data API is not making a small mistake, it is answering an entirely different question than the one it was asked, and everything downstream from that call is now built on the wrong foundation. The 2026 multi-tool review describes how this plays out across longer trajectories: as agents move from single calls to orchestrating several tools in sequence, the decision space shifts from a single binary choice into a series of coupled decisions within one task, where an early wrong selection invalidates every step that follows it. Ground truth for scoring selection is not hard to produce for known third-party APIs with stable schemas: it can come from annotated reference trajectories showing what the correct call sequence looks like, or directly from the API specification itself. Selection-level constraints are not limited to correctness either. ToolRLA's compliance dimension, R_cpl, carries a large negative penalty for categorically prohibited calls, and that penalty applies at the level of which tool got called, not how well its parameters were filled in. Some calls are off-limits regardless of how carefully they are constructed, and that distinction belongs entirely to the selection stage of the reward.
Rewarding parameter validity across schema correctness and argument values
Once tool selection is confirmed correct, parameter quality turns out to be at least two separate questions, not one. The first is schema validity: are the required fields present, and are they typed the way the API expects. The second is argument-value accuracy: do the actual values passed in correctly represent what the task called for. These two fail independently of each other, and conflating them into a single parameter score throws away information a reward function needs. ToolRLA's R_cor sub-scores keep tool-name correctness, required-tool coverage, and parameter accuracy as separate terms, so a call with the right structure but wrong values gets a different training signal than a call that is just missing required fields. This is the part of the reward design where the engineering gets more concrete. You can check schema correctness against the API specification without running the call at all, so you can compute a reward signal before the agent ever consumes a real API round-trip, and that saves cost and avoids unnecessary side effects during training. For an API where the schema is documented and machine-readable, this kind of check is cheap to build and cheap to run repeatedly. Argument-value correctness is a harder problem. A date can be in the exactly right format and still be the wrong date for the task. Checking values therefore requires comparison against a reference call or against the actual state of the environment, not just a check that the schema rules were followed. Comparison itself needs care before it is trustworthy: date formats, ID representations, and enumeration values can be equivalent in meaning without being identical as strings, so a reward function doing exact string matching on argument values will mark semantically correct calls as wrong, producing false negatives that quietly corrupt the training signal.
Rewarding execution outcome separately from call formation
A call can be perfectly formed, selecting the right tool and filling it with the right values, and still fail once it actually runs. That is why execution outcome has to be its own reward dimension rather than an assumed consequence of good parameters. Execution outcome asks two questions: did the API return success, and does the data that came back actually match what the task required. Neither question is answered by confirming the call was well-formed. A call can return HTTP 200 with a response body that does not reflect the operation the agent intended at all, so a reward function that stops at the status code is checking the wrong thing: it has to look inside the response. FC-RewardBench, a benchmark introduced alongside ToolRM, was built specifically to test reward models on tool-calling tasks, and it found that general-purpose reward models, trained mainly on natural language rather than tool use, frequently miss exactly these signals of whether a tool call actually did what it was supposed to do. That gap is why ToolRM proposes domain-specific outcome reward models instead of repurposing a language-quality model trained on text. Fabrication is also visible at the execution level, not just in theory. If an agent invents a Slack channel ID, it builds a syntactically valid call that sails through schema validation, and the mistake only shows up when the call actually runs and the API returns a channel_not_found error. A reward function that stops at parameter validity would have scored that call as correct right up until it failed. Efficiency belongs in this dimension too: ToolRLA's R_eff term penalizes unnecessary API calls, ones that succeed individually but add latency the task did not need, and that kind of waste is only visible once calls are actually being executed and timed, not at the selection or parameter stage. There is a harder problem sitting underneath all of this, though. Measuring execution outcome reliably means running the same call repeatedly and getting consistent results back, and a live third-party API does not promise that: response content can vary between runs, rate limits can throttle how often the call can even be attempted, and none of that variance has anything to do with whether the agent's behavior was good or bad.
Rewarding stateful side-effects as the final and most demanding dimension
The hardest reward dimension to get right is whether the full sequence of calls left the environment in the state the task actually required, and no single call's response can answer that question on its own. An agent can select the right tool, fill in the right parameters, and get back a response that looks like success, and the task can still have failed if the underlying data was never actually changed the way it needed to be. This is the dimension that a create-then-read pattern is built to test: an agent creates a customer record, then later reads it back to confirm it exists. When that sequence runs against a mock configured to return preconfigured responses, the test proves nothing, because the mock returns its scripted "found" response to the read call whether or not the earlier create call did anything real. Run the same sequence against a stateful simulator: the read step in step three either finds the entity the create step in step one actually produced, or it does not, so the reward signal is grounded in something that actually happened, not something that was scripted in advance. The 2026 multi-tool review frames long-horizon orchestration as requiring the agent to track intermediate state and respond to execution feedback across the whole trajectory, and stateful side-effect reward is the formal version of that same requirement, built into the scoring function itself. Taken together, the four dimensions this piece has walked through form a chain rather than a list: format validity gates whether tool selection reward even applies, tool selection gates parameter reward, parameter quality shapes execution outcome, and execution outcome feeds into whether the final state of the environment was actually correct. ToolRLA's multiplicative structure inside R_cor makes that chain of dependency explicit, so you do not leave it as an assumption buried in the training data. But none of this is computable without an environment that can actually hold state across the steps of a call sequence and return it faithfully when asked.
Stateful, repeatable environments as a prerequisite
Everything described above, format checking, tool-selection scoring, parameter validation, execution-outcome checking, and stateful side-effect assessment, depends entirely on an environment that can maintain consistent state across a sequence of calls, repeat that behavior identically across many training runs, and do so without hitting rate limits or exposing real credentials. Live third-party APIs and stateless mocks each fail at least one of those requirements, and neither can satisfy all of them at once. Live APIs fail on repeatability: response content is not guaranteed to be identical run to run, rate limits throttle how many training episodes can even be attempted in a given window, and state shared across concurrent training runs means one run's actions can silently affect another's results. Stateless mocks fail the opposite way. A mock configured to return a fixed response to a GET request has no memory of whether an earlier POST request actually created anything, because it always returns the same canned response no matter what came before it, which makes it structurally incapable of supporting the kind of side-effect reward described in the previous section. ToolRLA's own training pipeline shows how much this infrastructure matters at every stage: its SFT cold-start phase uses trajectories verified inside a sandbox to establish basic tool-invocation competence before the GRPO and DPO stages refine behavior further, so the fidelity of that sandbox environment shapes the quality of the whole three-stage pipeline from the very first step. Fault conditions matter too. Training an agent to handle rate-limit errors, malformed responses, and timeouts requires an environment that can produce those conditions on demand, because a live API will produce them unpredictably and often at the worst possible moment for a training run, while a controlled environment can inject them exactly when the training process needs to test for resilience. Finally, the data inside that environment has to look like real data. A sandbox that starts out empty and returns no records is not useful for training, because the agent never has to practice the retrieval and disambiguation work that real APIs constantly demand, and an empty environment hides exactly the argument-value mistakes that realistic, pre-seeded data would expose. Decomposed reward gives you the vocabulary to describe what went wrong and where in a training process. A stateful, repeatable environment is what makes any of those four scores trustworthy enough to train on.